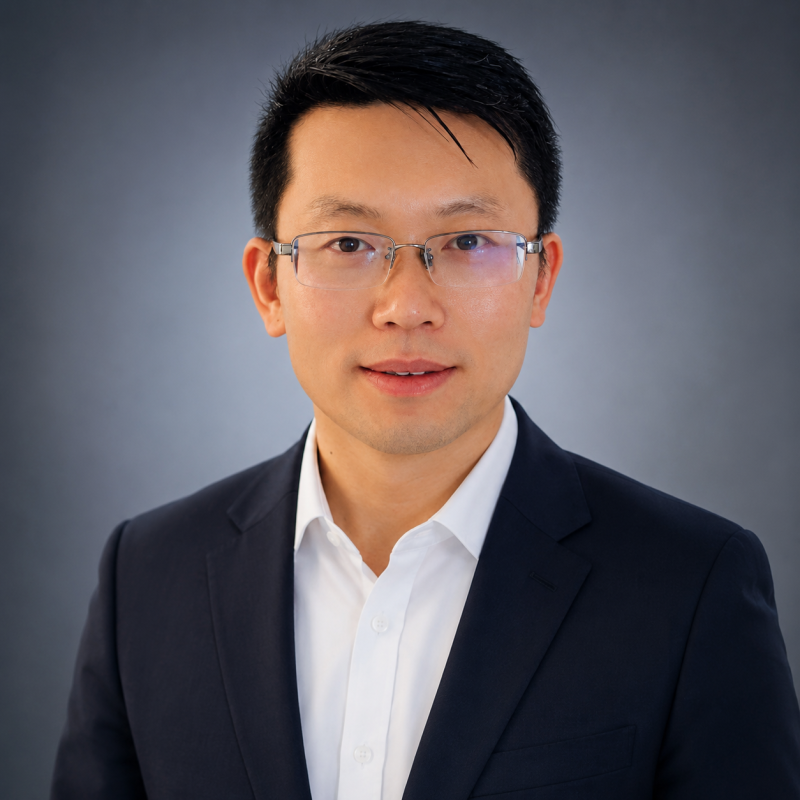
Leilei Zhou, Ph.D.
Leilei Zhou, Ph.D.
Open to Quantitative Research & Leadership Roles

Hello, I'm Leilei Zhou, Ph.D.

Quantitative Researcher | Systematic Research | Statistical Modeling

Ph.D.-trained quantitative researcher with 8 years of experience building, validating, and productionizing statistical and machine-learning models at J.P. Morgan. 4 years of quantitative team leadership with deep expertise in state-space models, factor research, credit and macro modeling, robust backtesting, and high-performance financial data pipelines.

Leilei Zhou, Ph.D.
West New York, NJ

Core Tech Stack & Competencies

Quantitative Research

Time-Series ForecastingState-Space ModelsKalman FiltersBayesian EstimationTime-Varying VARPCALinear / Logistic RegressionXGBoostADF TestsResidual Diagnostics

Systematic & Market Research

Factor ConstructionSignal EvaluationInformation Coefficient (IC)Walk-Forward OptimizationCross-ValidationRegime-Switching ModelsTransaction Costs & Slippage ModelingRisk Attribution

Data & Production Engineering

Python (Pandas, NumPy, Statsmodels, Scikit-learn)RSQLApache SparkDuckDBDockerGitCI/CDpytestLinuxLLM / MCP Research Tooling

Domain & Leadership

Team Leadership (Lead Quant)Institutional Capital ModelingCorporate Credit & Distance-to-DefaultMacro & CDX HY SpreadsDuration & ConvexityOut-of-Core Data Engineering

Featured Projects

Handcrafted web applications, tools, and open-source packages.

All Projects
Systematic Multi-Factor Equity Engine & Portfolio Optimization

Systematic Multi-Factor Equity Engine & Portfolio Optimization

Orthogonalized multi-factor equity strategy combining momentum, low volatility, and volume reversal signals with rolling beta neutralization and MAD outlier filtering.

PythonFactor ResearchBarra AttributionTCANumPyBacktesting
Recursive State-Space & Kalman Filter Engine

Recursive State-Space & Kalman Filter Engine

Productionized statistical library modeling time-varying parameters, latent macro regimes, and multi-asset sensitivities with Bayesian recursive estimation.

PythonState-SpaceKalman FilterTime-SeriesStatsmodels
High-Throughput Panel Data Pipeline (Spark & DuckDB)

High-Throughput Panel Data Pipeline (Spark & DuckDB)

High-performance vectorized data processing pipeline processing 20+ years of panel data across 50M+ facilities with out-of-core memory efficiency.

Apache SparkDuckDBNumPyPythonSQLHigh-Performance

Latest Articles

Thoughts on software engineering, architecture, and technology.

Read All

Moments & Photography

A collection of frames captured across travels and daily life.

View Gallery

Visitor Guestbook & Thoughts

0

Feel free to leave a comment, say hi, or share your feedback below!

Private Guestbook: Only you and Leilei can see your messages and replies. Other visitors cannot see your comments.
Avatar
Markdown formatting supported0/2000